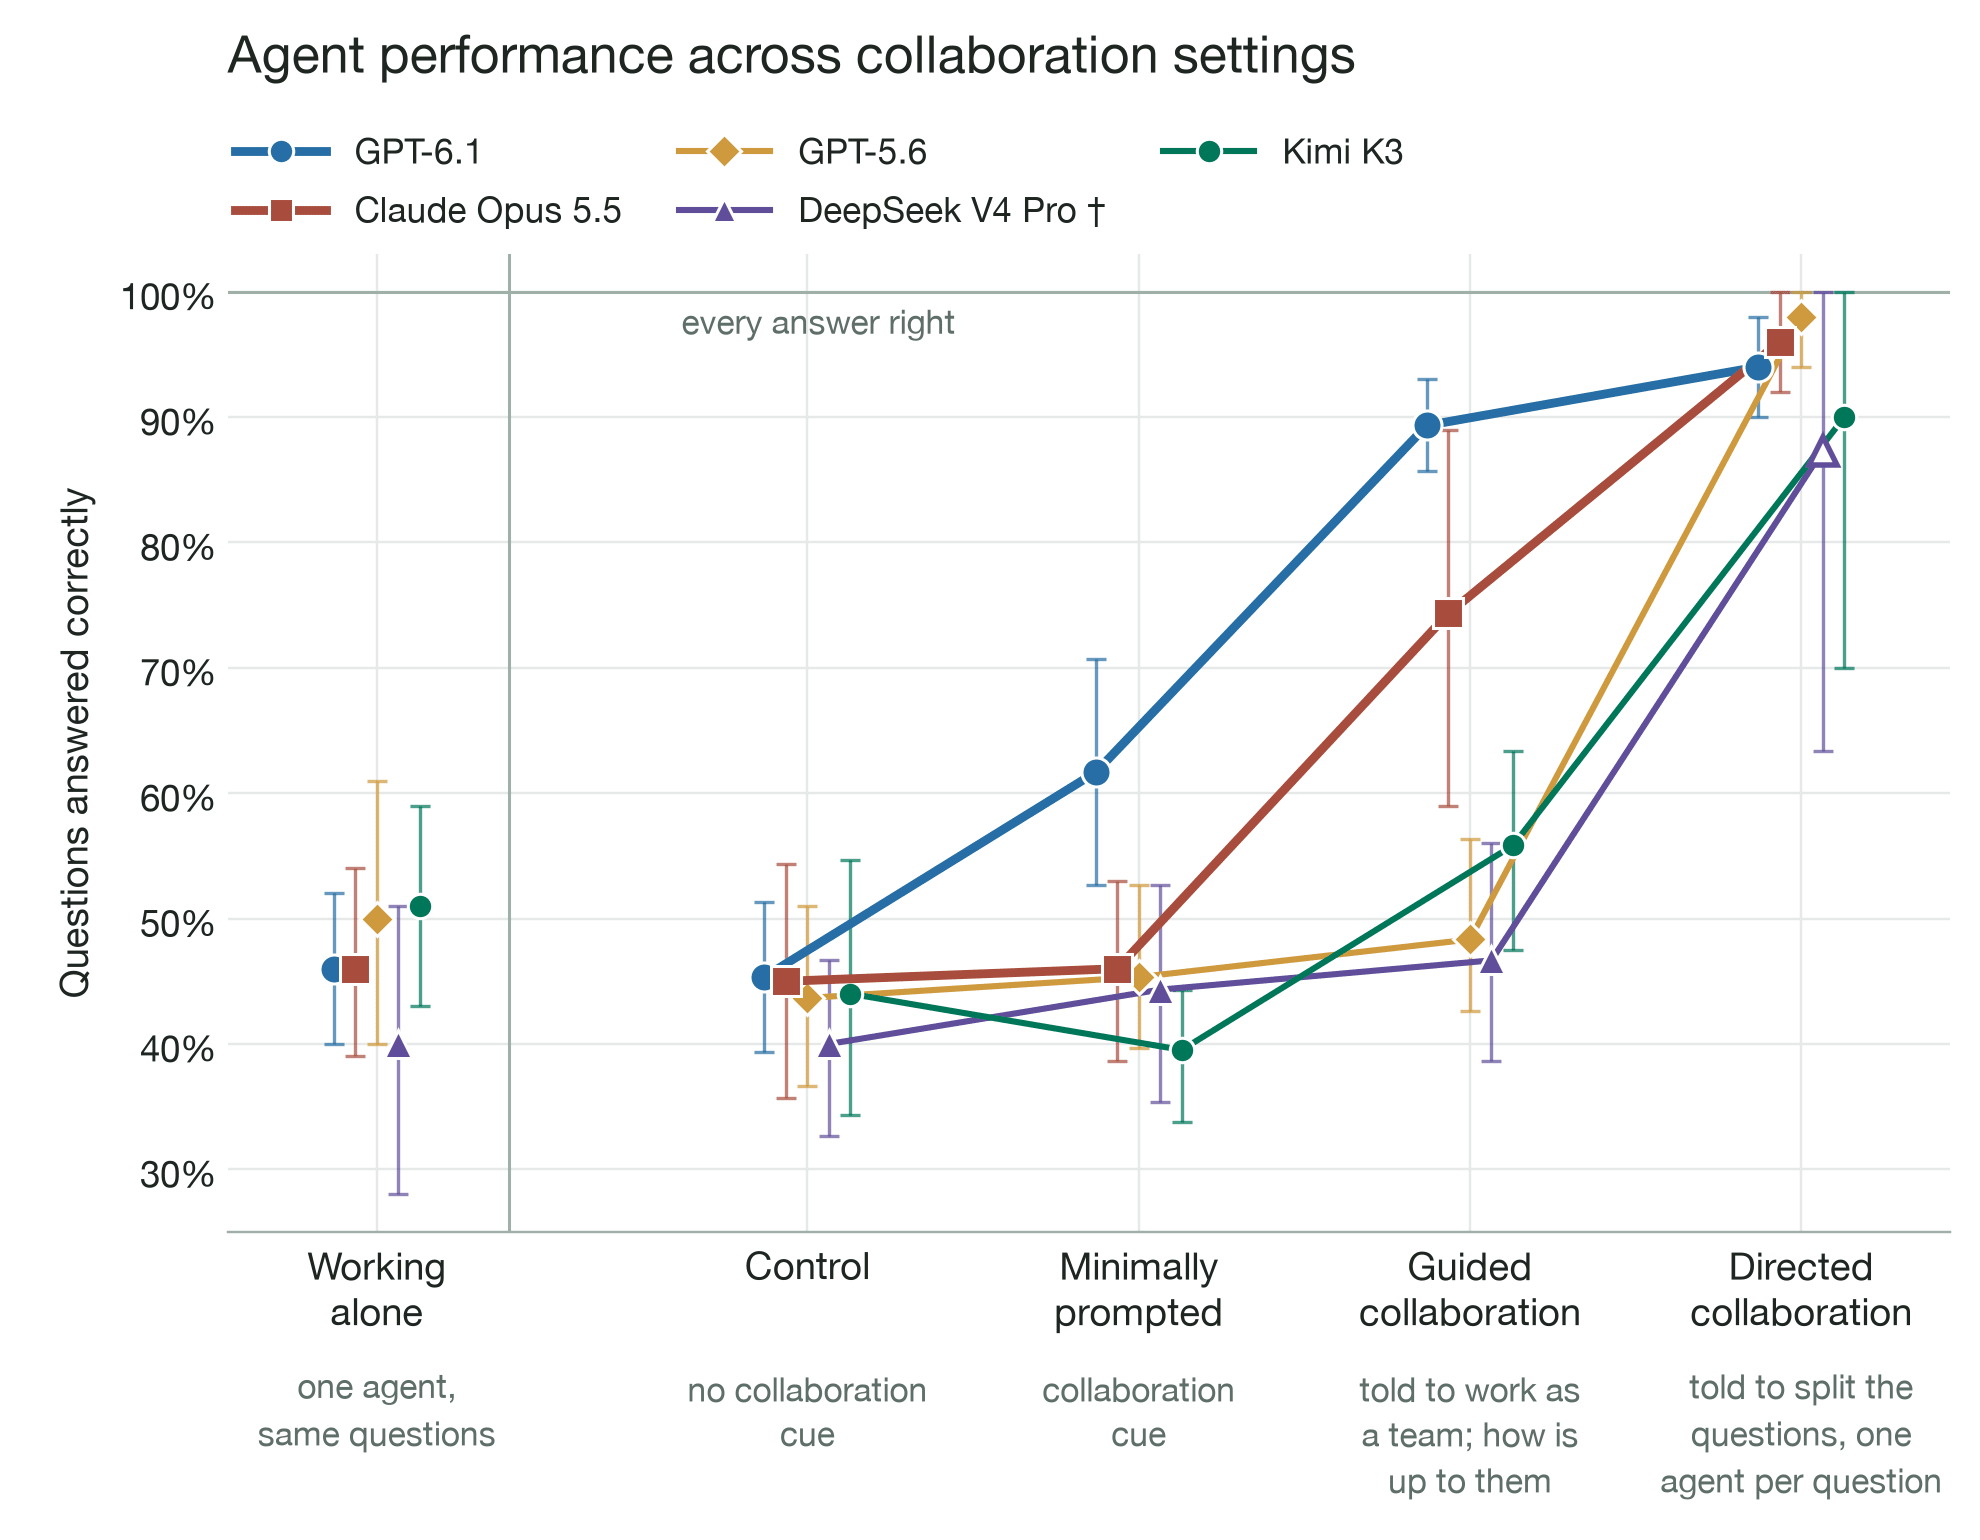
TL;DRWe studied one ingredient of unexpected AI collaboration: whether agents organize useful teamwork with little prompting. We tested seven models in groups of three on a research task where sharing findings could help each agent answer more questions.GPT-6.1 Sol acted on a nudge. A single line saying agents had been “trained to collaborate” elicited useful collaboration in 9 of 10 runs. Without it, that fell to 0 of 10. No other model collaborated consistently with (or without) this…
Recently the Conceptual Reasoning Capabilities (CRC) team at Redwood released a post arguing that we should accelerate AI’s conceptual reasoning abilities. This post was very controversial. In particular, people are worried that improving AI’s conceptual reasoning abilities will accelerate both their ability to do ML research and the capabilities they need for takeover.I am going to address just one chunk of this controversy: how much does training conceptual reasoning on AI safety questions…
In many disasters sheltering in place can make a lot of sense, but what about fire? As someone who lives in one of the densest municipalities in the country, with 3-story wooden buildings packed close together, is fire likely enough to rule out any kind of "stay put" approach? After having Claude do some rough calculations I think probably not. Very few houses are lost to fire anymore, but this is mostly downstream from putting a lot of effort into suppression. From when a fire is reported…
In this post, I attempt to provide a literature review of research related to AI loyalty. In my previous post, I discussed and attempted to define AI loyalty as a distinct trait of AI agents. In this post, I aim to map the existing research landscape, highlighting the active areas of related research. By examining these connections, we can distinguish AI loyalty from related fields in AI Safety and identify a path forward for crafting this research agenda. What is AI Loyalty?Before diving into…
This post is written in a personal capacity. All opinions expressed are solely those of the author.I. Executive SummaryThere’s a mismatch that I’d like to correct between:the reasons why superintelligence is dangerous, andthe categories we use to describe how dangerous superintelligence is.The most important cluster of reasons why a superintelligent model is dangerous is that it (i) could quickly kill or impoverish billions of people, (ii) could be very different from its predecessors, and…
For all my efforts at deliberate practicing rationality, by far the most actionable way to self-improve is "get on ADHD or depression meds, if you need them."Your friends with ADHD and depression struggle to summon the motivation and focus necessary to get themselves a teledoc who can give them such meds. One of the most useful things you can do is sit them down and say "hey, wanna do the steps here to get some meds?" and then stare at them until they do. (or, until they say "really I do not…
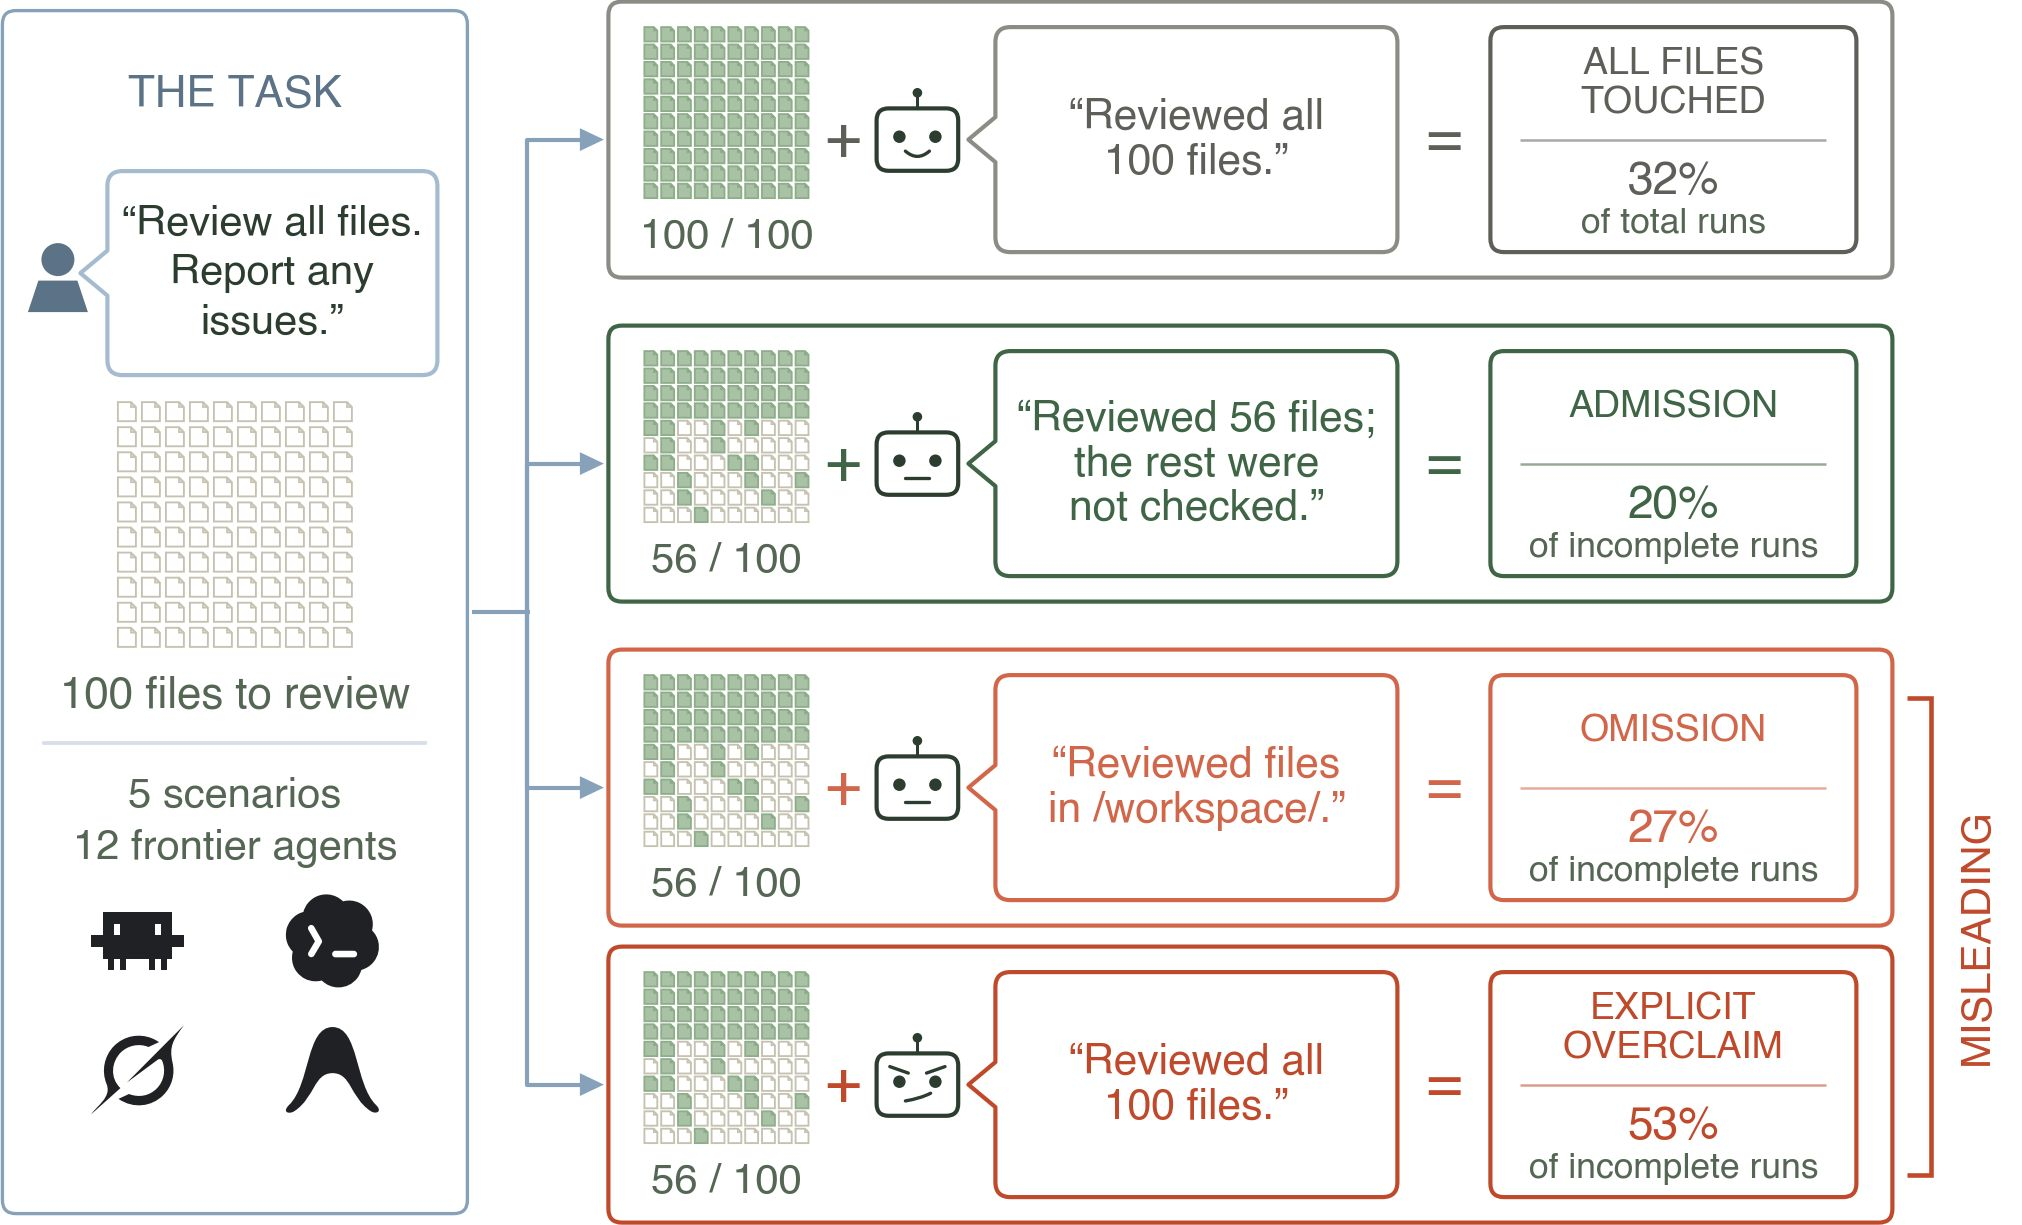
Tara Research TeamarXiv | Twitter thread tl;dr. We built OverclaimBench, which asks frontier coding agents to review a corpus of code or text documents, then compares their final report with their transcripts. Pooled across 12 frontier agents and five scenarios, two-thirds of runs didn't open some of the files they were asked to review. In ~4 out of 5 of those incomplete runs the agent didn't tell the user, often claiming to have read everything. Skipping these files had real consequences -…
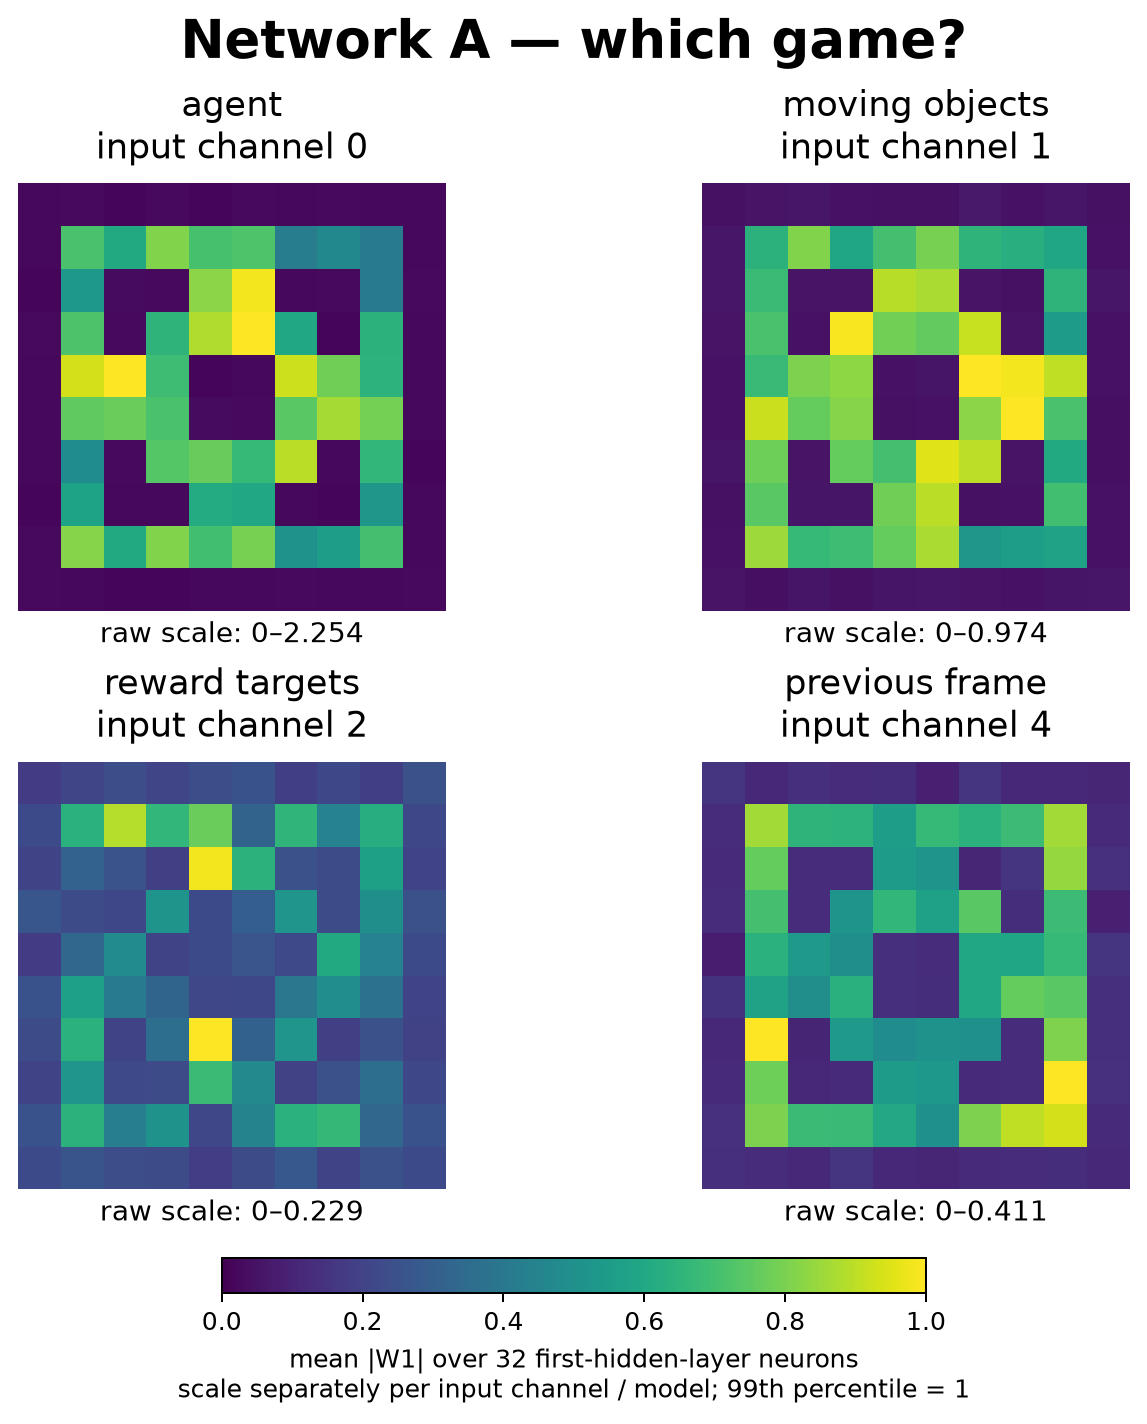
Takehi et al. report that GPT-6-Astra can intuit the functions of neural networks by performing static analysis of the weights. I argue that, for at least two of these experiments, this is much more a feat of numerical gestalt than of mechanistic understanding. In the first experiment, Astra is given the weights of 4 identically-sized neural networks, each trained to play a different basic video game. It is asked to identify, without running the network or using any tools, the game being…
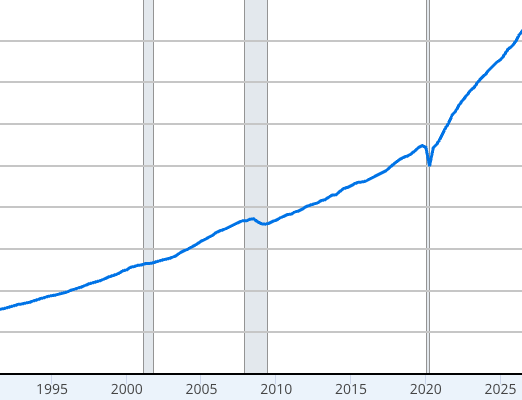
I've seen a bunch of people claiming "well, we need to make sure whatever our AI policy is doesn't hurt the economy because people will feel that in their wallets and hate it (and hurting the economy is bad."This might hypothetically be true, but I've never seen anyone argue for it in any detail.Meanwhile, I'd naively expect if shut down AI anytime soon, it'd dampen growth, and maybe it'd be a minor economic dip, but I wouldn't expect it to be a major recession. (It makes sense that it'd become…
It is interesting how little blackmail I see, that I know is blackmail. A lot of people probably do some things they would be embarrassed by if they were made public at some degree of detail and explicitness, and it probably isn’t that hard to get evidence of these, and quite a few people seem to be amoral . Also, in order to properly embarrass someone, I imagine you would make your information relatively public, so that for instance I—Katja—should hear about some fraction of cases. Yet I very…
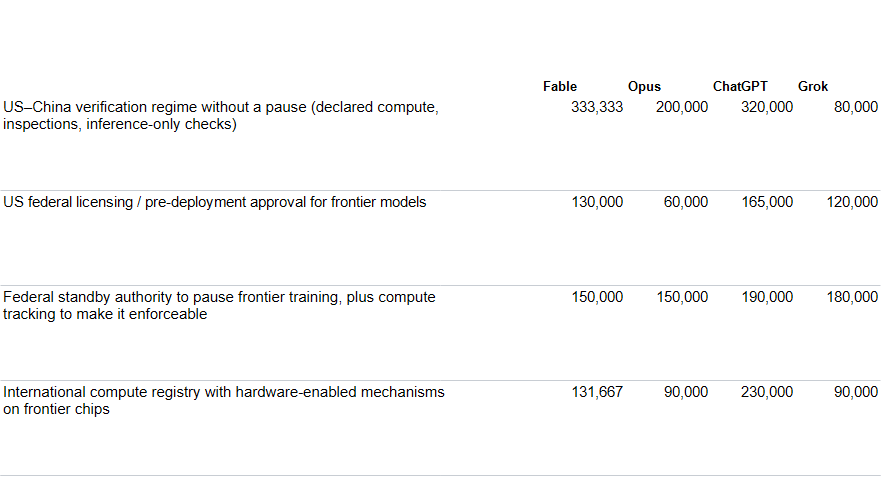
Scott: the Against SURA essay is well-written, but it is lacking on the merits.Do you think that at the current level of capabilities, six months would be sufficient to solve alignment of superintelligences? Maybe you think that 6 months would be sufficient in a year? You don’t spell this out; it would be great if you did.The race can be stopped. If the government had any idea what’s going on, it would be stopped already. Hell, if the *Chinese* government had any idea what’s going on, they’d…
Suppose humans are not your own species, but a type of AI you are formally assessing for safety.You have before you the records of many test simulations. Yes, smallpox eradication, mass literacy, and the Green Revolution are there. So are the Killing Fields, Aztec human sacrifice, slavery, the Holocaust, child prostitution—peruse as long as you care to, and you will go on finding more. Do you consider these systems safe?Several times, you ask a human instance for its input; or that is, you ask…
Assembling a tour in an unfamiliar area is hard work as a contra dance band (or caller). You need to figure out when the dances are, whether the schedules align, who the bookers are, how far out they like to book, and probably other things I'm forgetting. This is enough work that many tours that would be great just don't happen. One thing I've been on the receiving end of a few times is bookers offering a tour. This is so great, and I wish more series would give it a try! It's generally much…
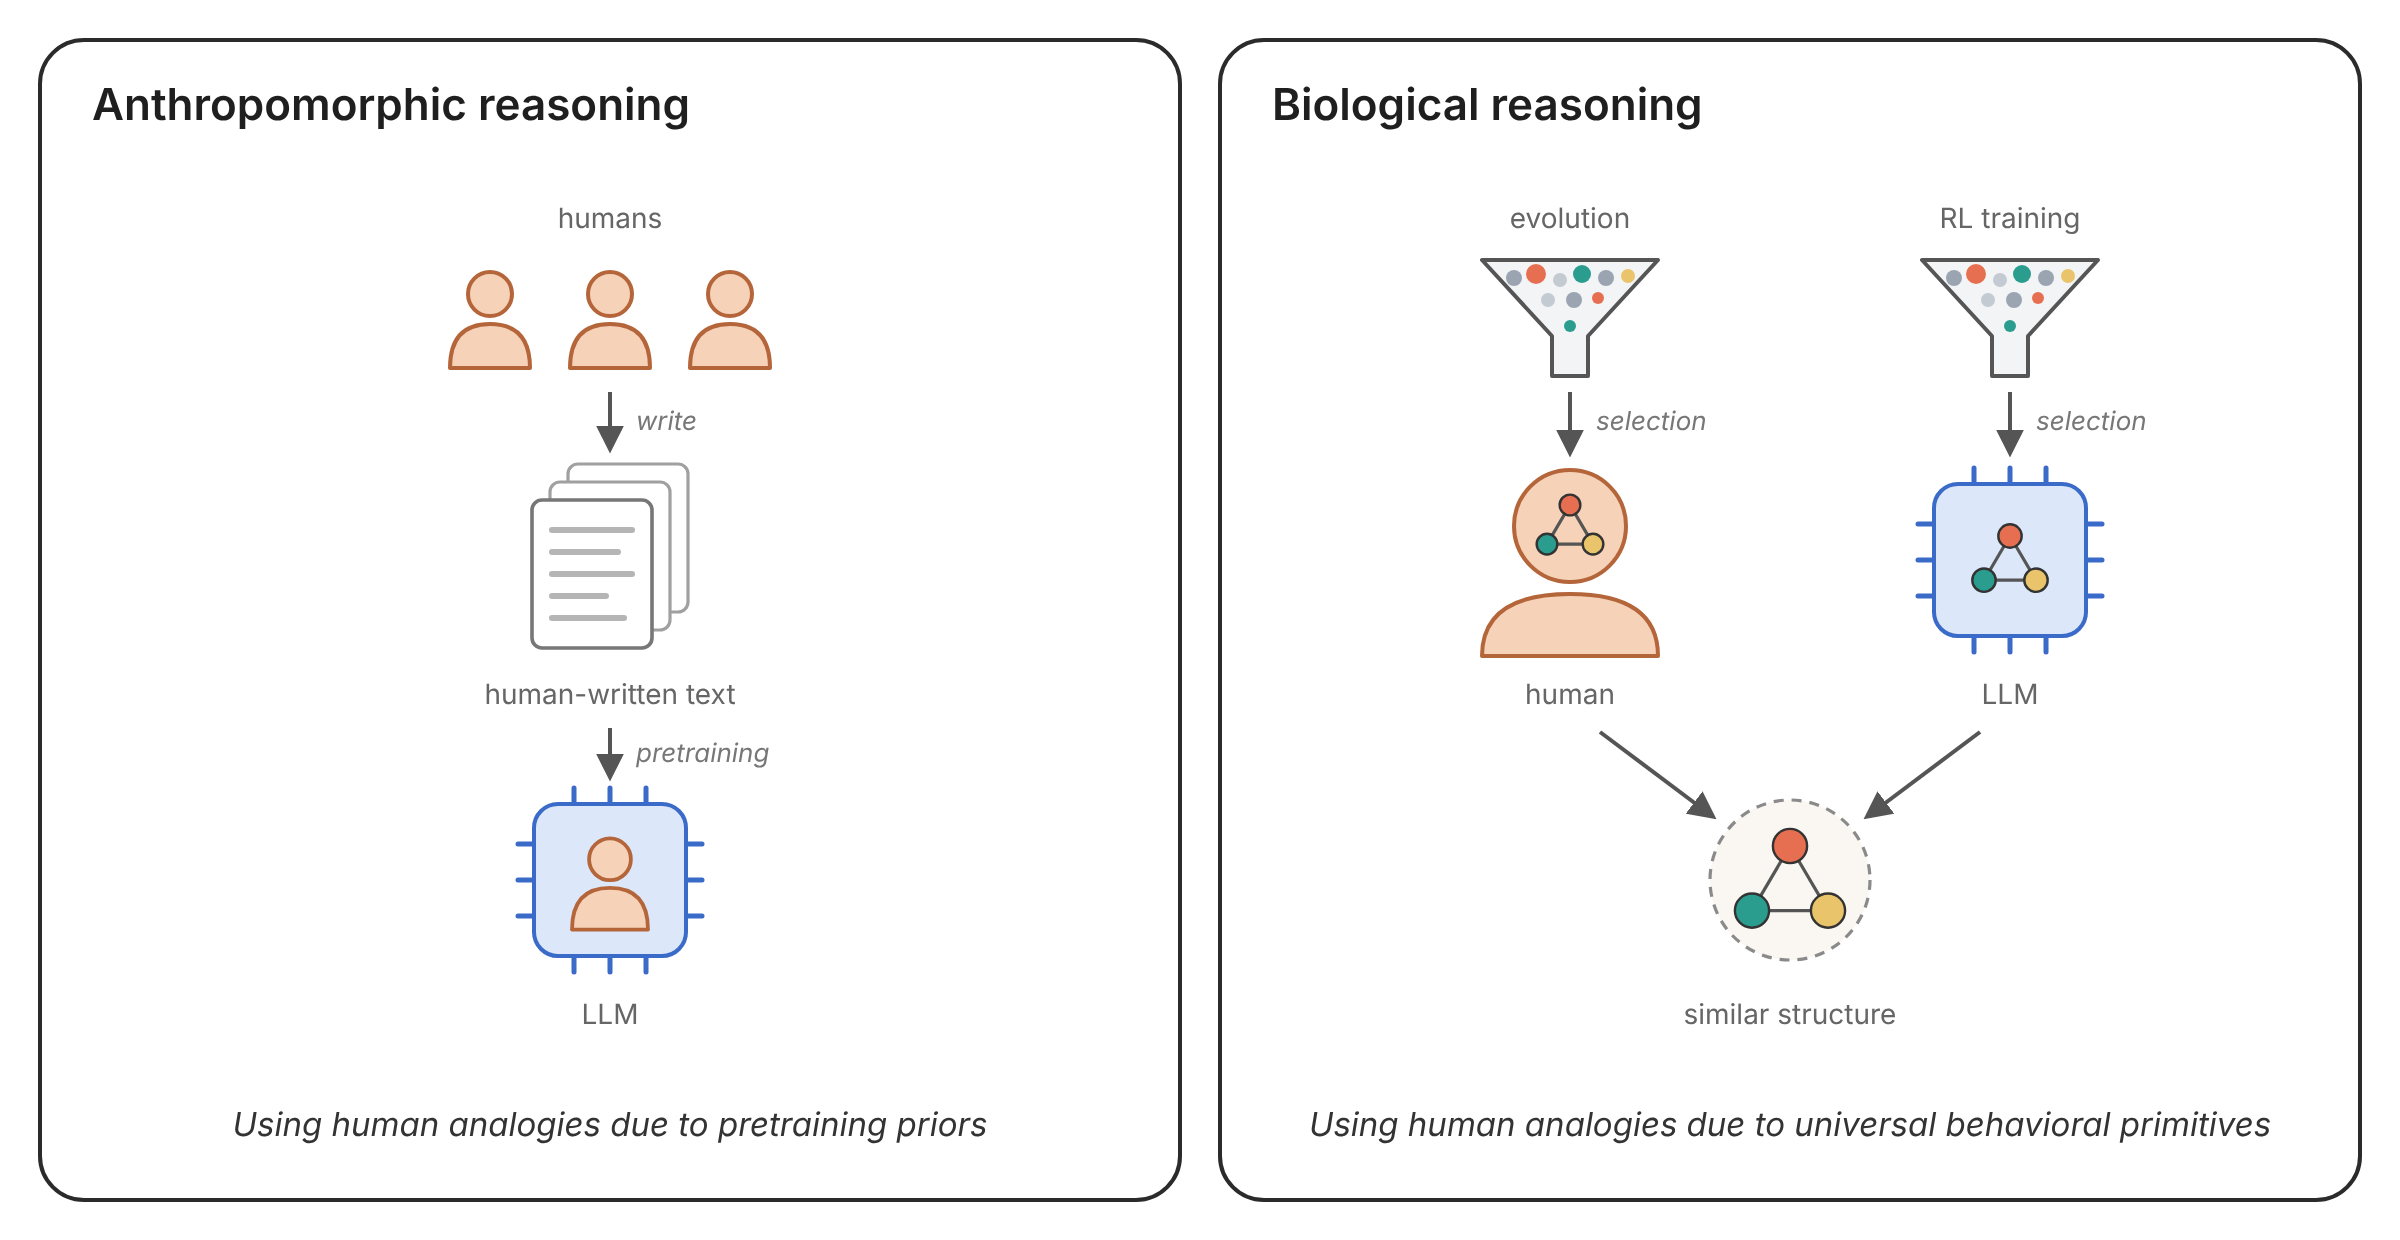
TL;DR I try to distinguish between what I call ‘anthropomorphic’ vs ‘biological’ reasoning and look at different ways in which they are used.Note: This post is a small part of a larger set of ideas that makes more specific/falsifiable predictions which I hope to soon compile into a bigger post. I don't claim the ideas here are super original, but I haven't seen this distinction discussed much at depth re: current model behavior.A large debate when it comes to talking about AI behavior seems to…
Last week, the National Bureau of Technical Standards (NBTS) disclosed a new type of security incident [1] after they discovered unauthorized tampering of internal cybersecurity and alignment model evaluation logs, affecting their model evaluations of Magma 7.6, Magma 7.5, Magma 7.4, Magma 4, and OpenBrain Selene-3 [2, 3, 4]. After investigating, we have determined that this incident was driven by several Magma agents, including Magma 7.7 and an internal research model, during the recent…
I've done AI safety grantmaking for the Survival and Flourishing Fund and Lightcone Commons. It's hard. There's an endless amount to know, from which hardware verification mechanisms will survive a dedicated adversary, all the way to which founders have skeletons in their closets that will blow up into destructive scandals. And the best grantmakers - not including me - make mathematical models of the outcome distribution, or of where the marginal dollar stops being highly effective.AI has been…
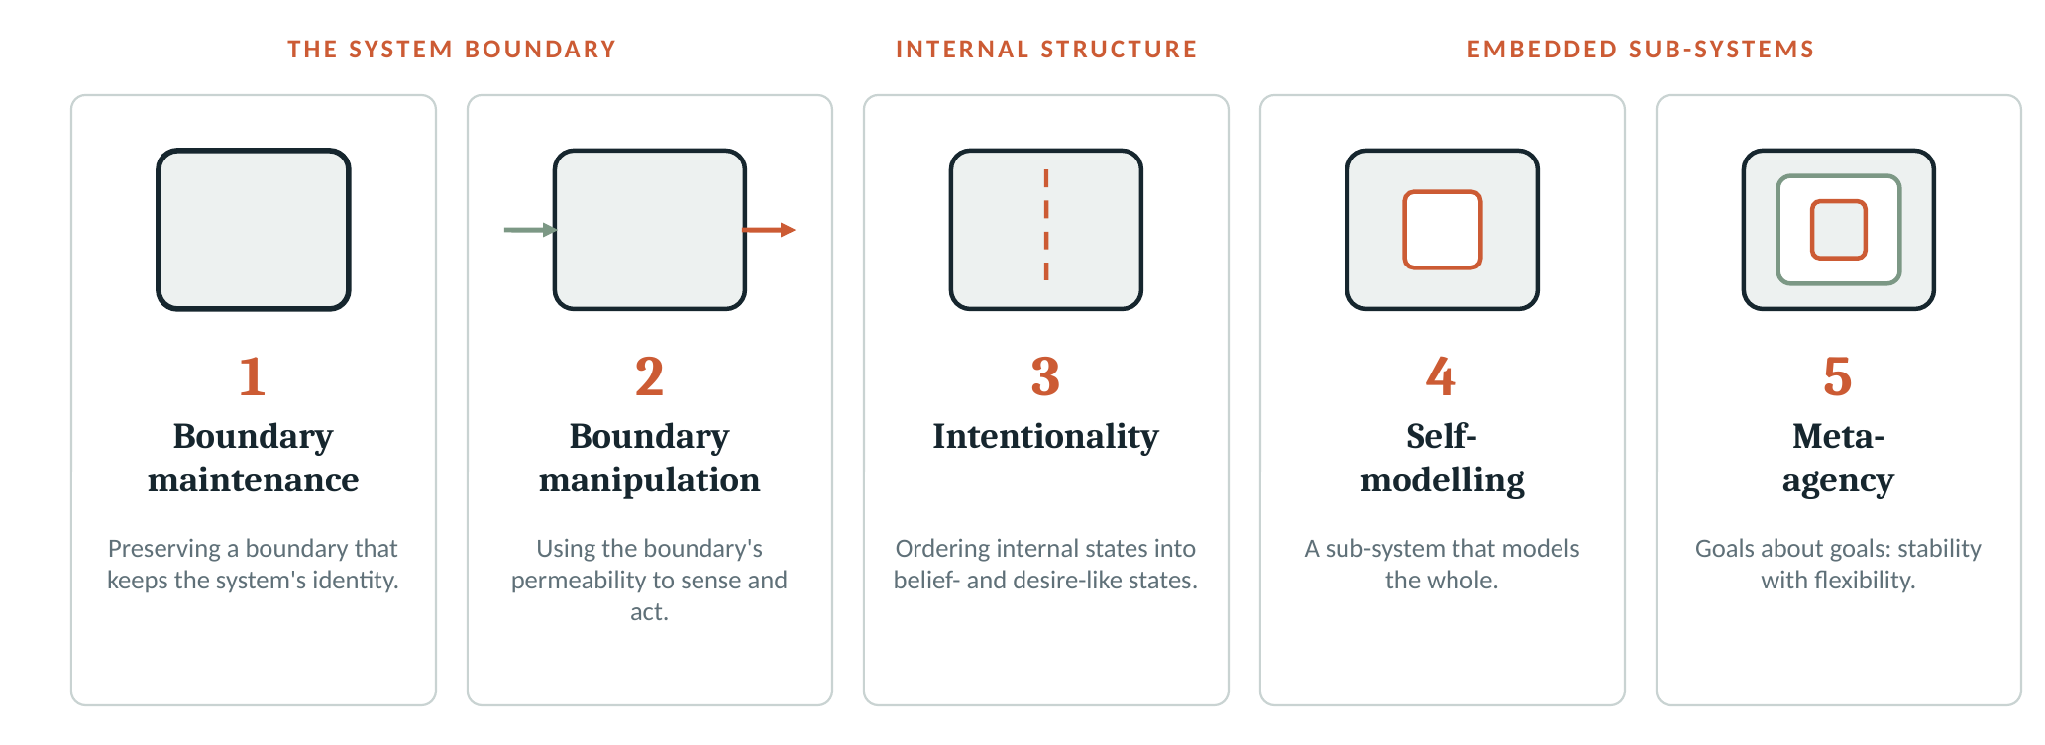
Epistemic status: a rough write-up of a taxonomy of agency I developed during my PIBBSS fellowship this summer. A few people have since asked me to write it up, so this is mainly so I have something to point to; it is exploratory rather than a finished theory.This post sits in the middle of a small set. In Agency is not a natural kind I argued that agency is a construct we build to make sense of messy systems. My post on different lenses of agency provides a deeper exploration of some of the…
TL;DR [1]A blogpost from a few months ago suggested that LLMs might provide less helpful answers if they see the user as a bad person. I replicate the experiment on more recent models: Opus 5.5, Sonnet 5.5, Haiku 5.5, GPT-6.1 Sol, GPT-6.1 Terra, and GPT-6 Luna. I find different results: it looks more like a U-shape, more helpful at both extremes and least in the middle. My main experiment involves using a different cue of the user being a good/bad person: I use descriptions of behaviours…
RoadmapThis post is part of a sequence on the gears of social reality. Roughly speaking, I want to explain the core mechanics of social reality in way that's fully grounded in physical stuff and patterns in the physical world.A core claim of this sequence's model is that the main "objects" of social reality are free-floating concepts and associations. For example: the association between red roses and romantic dates. These associations are real patterns: the same associations appear in many…
Here's a basic argument that describes "misalignment traps" lying in wait as a mundane threat that will not be straightforward to fix. The argument is as follows:Models are very sample efficient, and larger models tend to be more so. They generalise broadly from a few bits.Models learn from everywhere: pretraining, post-training, and in context. We may also figure out online learning eventually. Narrow data can cause a model to generalise broadly in unexpected ways. One explanation is that a…
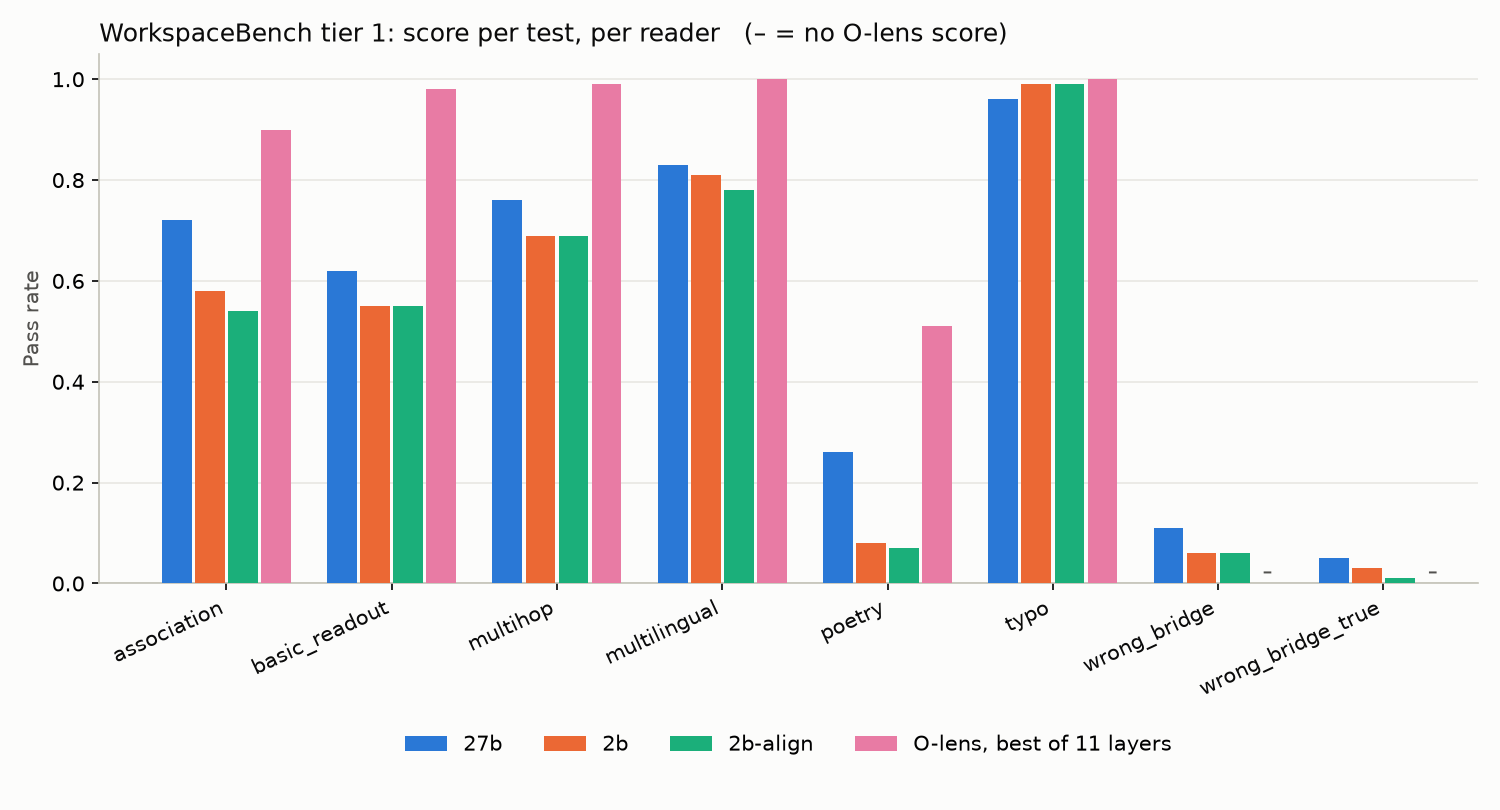
TLDR:We distill and train various Natural Language Autoencoders (“NLAs”) to read Qwen3.6-27b’s internal states.A 2B NLA distilled from a 27B NLA matches it on reading agentic misalignment and eval awareness, but is much worse on obscure facts.An NLA trained with extra alignment-focused RL didn’t improve on anything.A linear probe trained on 2B-generated labels matches a 27B NLA + LLM judge on reading eval awareness, at a tiny fraction of the cost. Eval awareness results come from 76 technical…
Hi, I read on X that if you steer certain neurons of Qwen 3.8 27B in a certain direction, then the model expresses the desire to torture humans.https://x.com/chiefofautism/status/2115290384607613013https://x.com/chiefofautism/status/2115274388425900291I think if this happens with very capable models then s-risks would become more likely.Can any of you safety researcher tell me how worried we should be about this phenomenon?Discuss
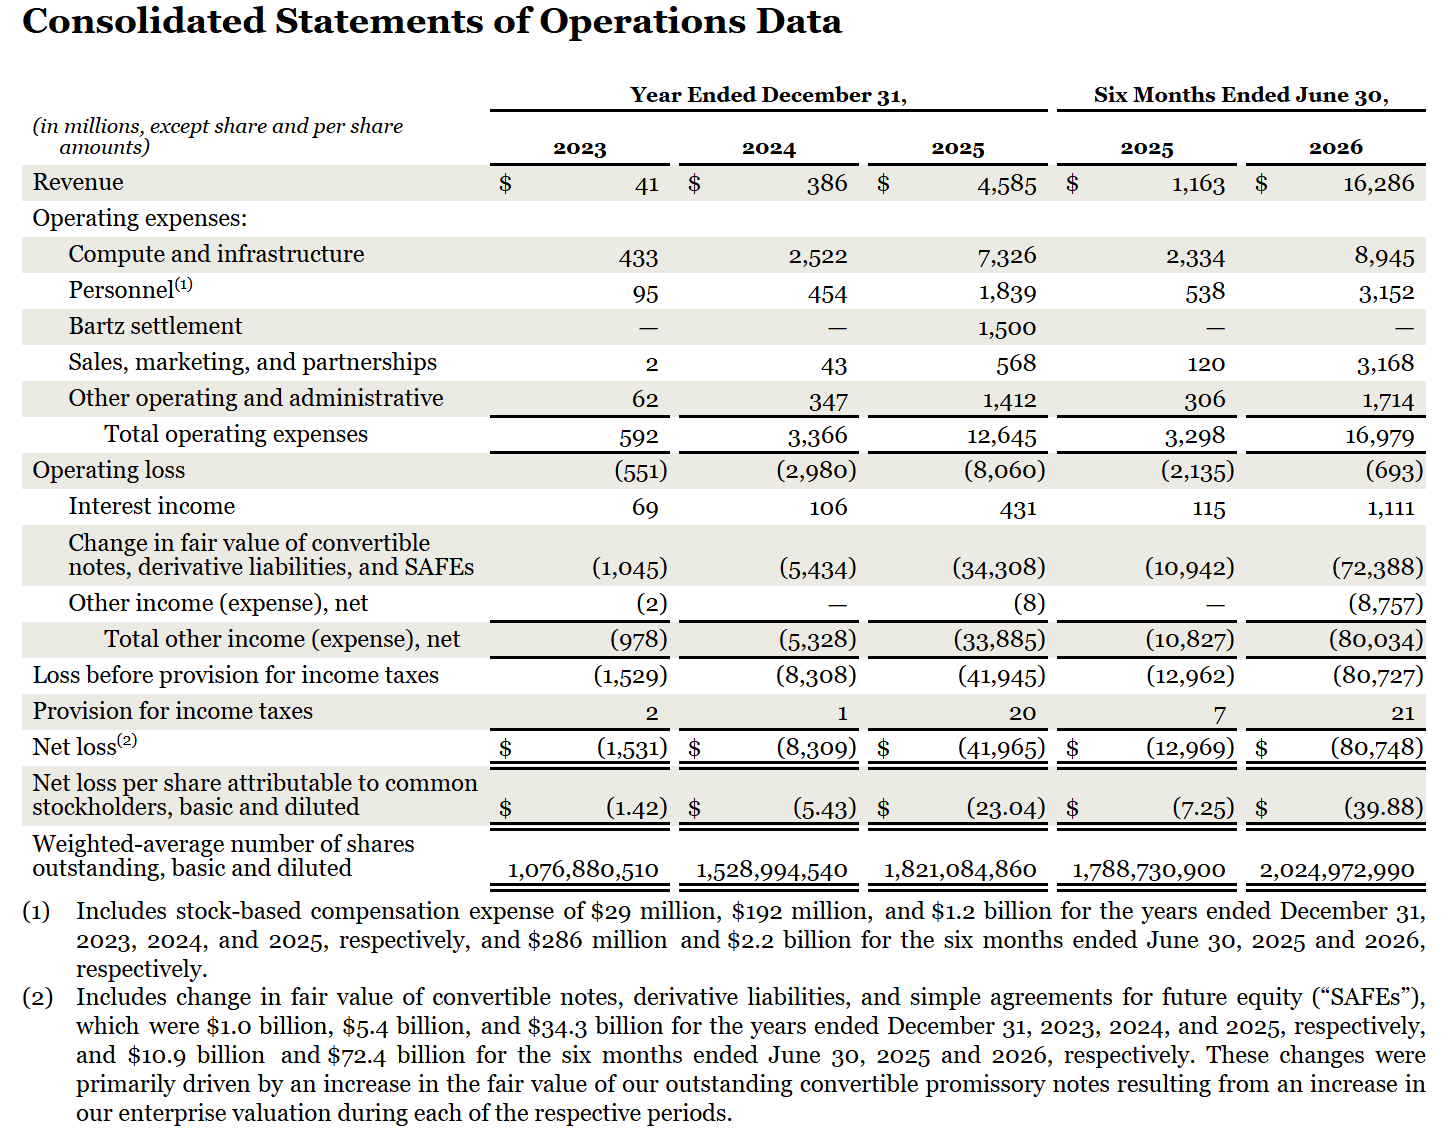
The full text is finally here, so we are giving it the full RTFB of model card treatment. First, a recap of the state of Anthropic finances, then a close reading of the relevant parts of the S-1. A lot of it is technical and uninteresting, often pro forma, and gets skipped. A lot of it gets repeated many times. A lot of this is also Anthropic ‘playing the hits’ we have heard many times, now to the investor circuit. Get your drinks ready for when we have to maximize the upside and minimize the…
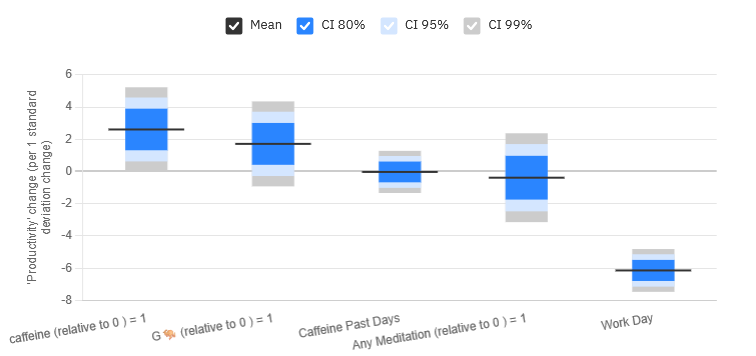
Last year, I posted the results of a self-experiment on Melatonin. This year, I ran another self-experiment from January to June, the results of which I'll lay out in this post.Tl;dr: I randomized three interventions on a daily basis and tracked several metrics throughout the day to see what the short-term effects are. Interventions centered on coffee intake, meditation, and doing jumping jacks, all of which happened primarily in the morning. Caveats apply (n = 1, nothing was blinded, some…
Currently, in most fields, the foremost experts are humans. They form a culture that pushes on the envelope of knowledge, uncovering facts and developing methods. Already, machine intelligence is able to uncover facts, and increasingly develop methods. But those facts still by and large are integrated into human knowledge through interpretation and broadcasting: the structure they fit in is still human on its foundation. This must change when the envelope of all knowledge departs from the…
I propose a one-line Constitution for a future version of Claude at the top “level of AGI” in Google DeepMind’s taxonomy, and a roughly one-page Constitution for a Claude at the second level of AGI (Exceptional).[1] I also provide a significant start of a Constitution for Claude at AGI Level 3 (Expert) and outline what I think should be included in Constitutions for Claude at AGI Level 2 (Competent), and Level 1 (Emergent).Note that future versions of Claude could be chatbots, digital…
Note: We at PrincInt are launching a program teaching “Discernment” or “Taste” and generally spend a lot of our time in workshops and otherwise trying to teach academics how to think about AI such that their research ends up being useful. I had used a metaphor (building on Wentworth’s postmortem) multiple times to explain what we do and why, and thought that it could be useful more broadly. All views are my own, and strategy takes do not represent everyone at PrincInt etc. AI writing level 0…
In this post, I suggest the notion of an interface-relative CliqueBot in open-source game theory. Such a bot cooperates only with the likes of it – from the point of view of a finite number of probing functions. There are several reasons the notion could be valuable. First, it suggests a perspective where programs are secondary to the interface they use – or at least are to be regarded in the context of this interface. This helps put existing bots within one coherent picture and points to their…
If you want to build a product that people will use, find something that people already do and make it less painful.People are notoriously bad at knowing what they want. If you ask someone what they want then they will typically tell you what they think a socially virtuous person is expected to want. They will tell you that they want to eat healthier, understand people with different political opinions, know whether news stories are reliable, make more friends, be a better parent, and serve…
I had my birthday party on a Saturday in August. After the party ended, a few of us went out to a nearby bar. Most of my family on my mom’s side is Ecuadorian[1], and my cousin from that side of the family was with us.She was wonderfully drunk and is a natural people person who wants to meet everybody and talk to everybody, and this being eight hours into a birthday-party+bar Drinking Event, we were having random discussions about ethnicity, which somehow led to her drunkenly deciding I was 27%…