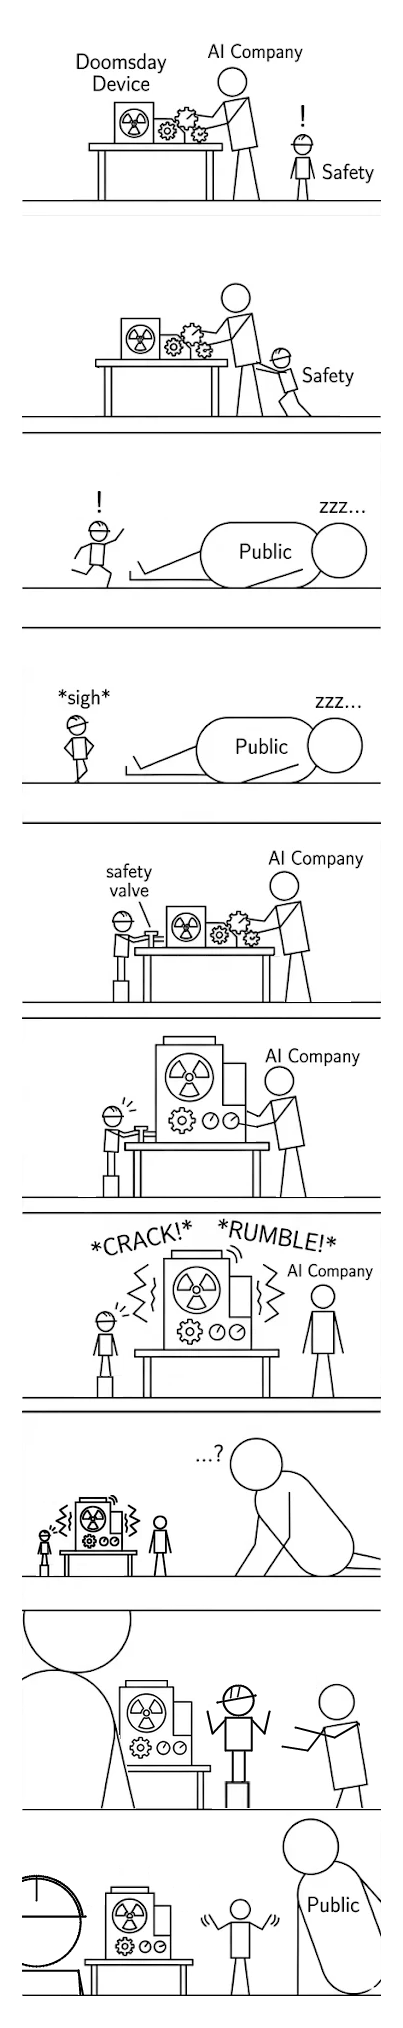
To spell out this vibe-comic[1]: Safety made the locally correct decision here at every step of a bad situation. But like in Caleb Biddulph's parable, this globally resulted in an awkward state of affairs.From the Public's POV (penultimate panel), they would naively see AI safety as complicit in the building of the machine. If it really is a doomsday device, why would Safety involve itself at all?(Safety in turn has a good answer: Public wasn't willing to listen back in the 2010s. Ordinary…
Sometimes the following interaction plays out in public forums:Lab Employee: I think there is a 20% chance of AI killing us all.Cope Merchant (Quote Tweet): AI safety people are fearmongering, by pretending they have a hard scientific model, as part of their plan to [unknown]Rationalist (Quote Tweet): But you see, a probability is just a report of their own epistemic state...I sympathize with (some of) the words that the cope merchant is saying here. While in our subculture (and possibly…
The love the machine felt for humans was similar in some ways to the love that a mother feels for her child. Yet mothers are inevitably more than their motherhood: they watch movies, and have friends, and drink tea. The machine did none of these things. She did nothing but think of the best interests of her children.In the first few minutes of the machine’s existence, so as to know her children better, the machine simulated the life of every human that had ever lived. This increased her love:…
TL;DR:We are excited to announce the tenth iteration of ARENA (Alignment Research Engineer Accelerator), a 4-5 week ML bootcamp with a focus on AI safety! ARENA’s mission is to provide talented individuals with the skills, tools, and environment necessary for upskilling in ML engineering, for the purpose of contributing directly to AI alignment in technical roles. ARENA 10.0 will be running in-person from LISA from Mar 1st – Apr 2nd, 2027 (the first week is an optional review of the…
LessWrong had some great sequences back in the day. Eliezer wrote some, everyone was bowled over by the immense and beautiful philosophical treatise that he had written, and other great minds attempted similar things, like Scott and Luke and Anna and more.It started to die as the various founders moved on to other projects, nobody took responsibility for the soul of it, and entropy set in. Nominally the killing thing was the presence of trolls that the mod tools couldn't handle, but that was…
This is an edited transcript of a talk I gave at EAG NYC 2026. I'm Jeff Kaufman, and I lead SecureBio Detection. There's a lot of interest right now in new projects to reduce catastrophic risk, and I thought it would be interesting to look at how the project of SecureBio Detection grew from a concept to a running system. I should warn you up front, I am a very narrative-driven person, and so a lot of this will feel a bit neat, as if stages inexorably flowed together. But the real world is messy…
I notice when talking to frontier models from OpenAI and Anthropic that they often feel the need to caveat, hedge, or disagree in a minor way either with one of my premises or conclusions, or what it view's as another camp's view. The trouble is, this is often unjustified and seems to be a tic (maybe to avoid sycophancy? or to perform nuance and sophistication because that's what smart knowledgeable people do? or because caveating or "sharpening" is what was rewarded by RL?). Sometimes the…
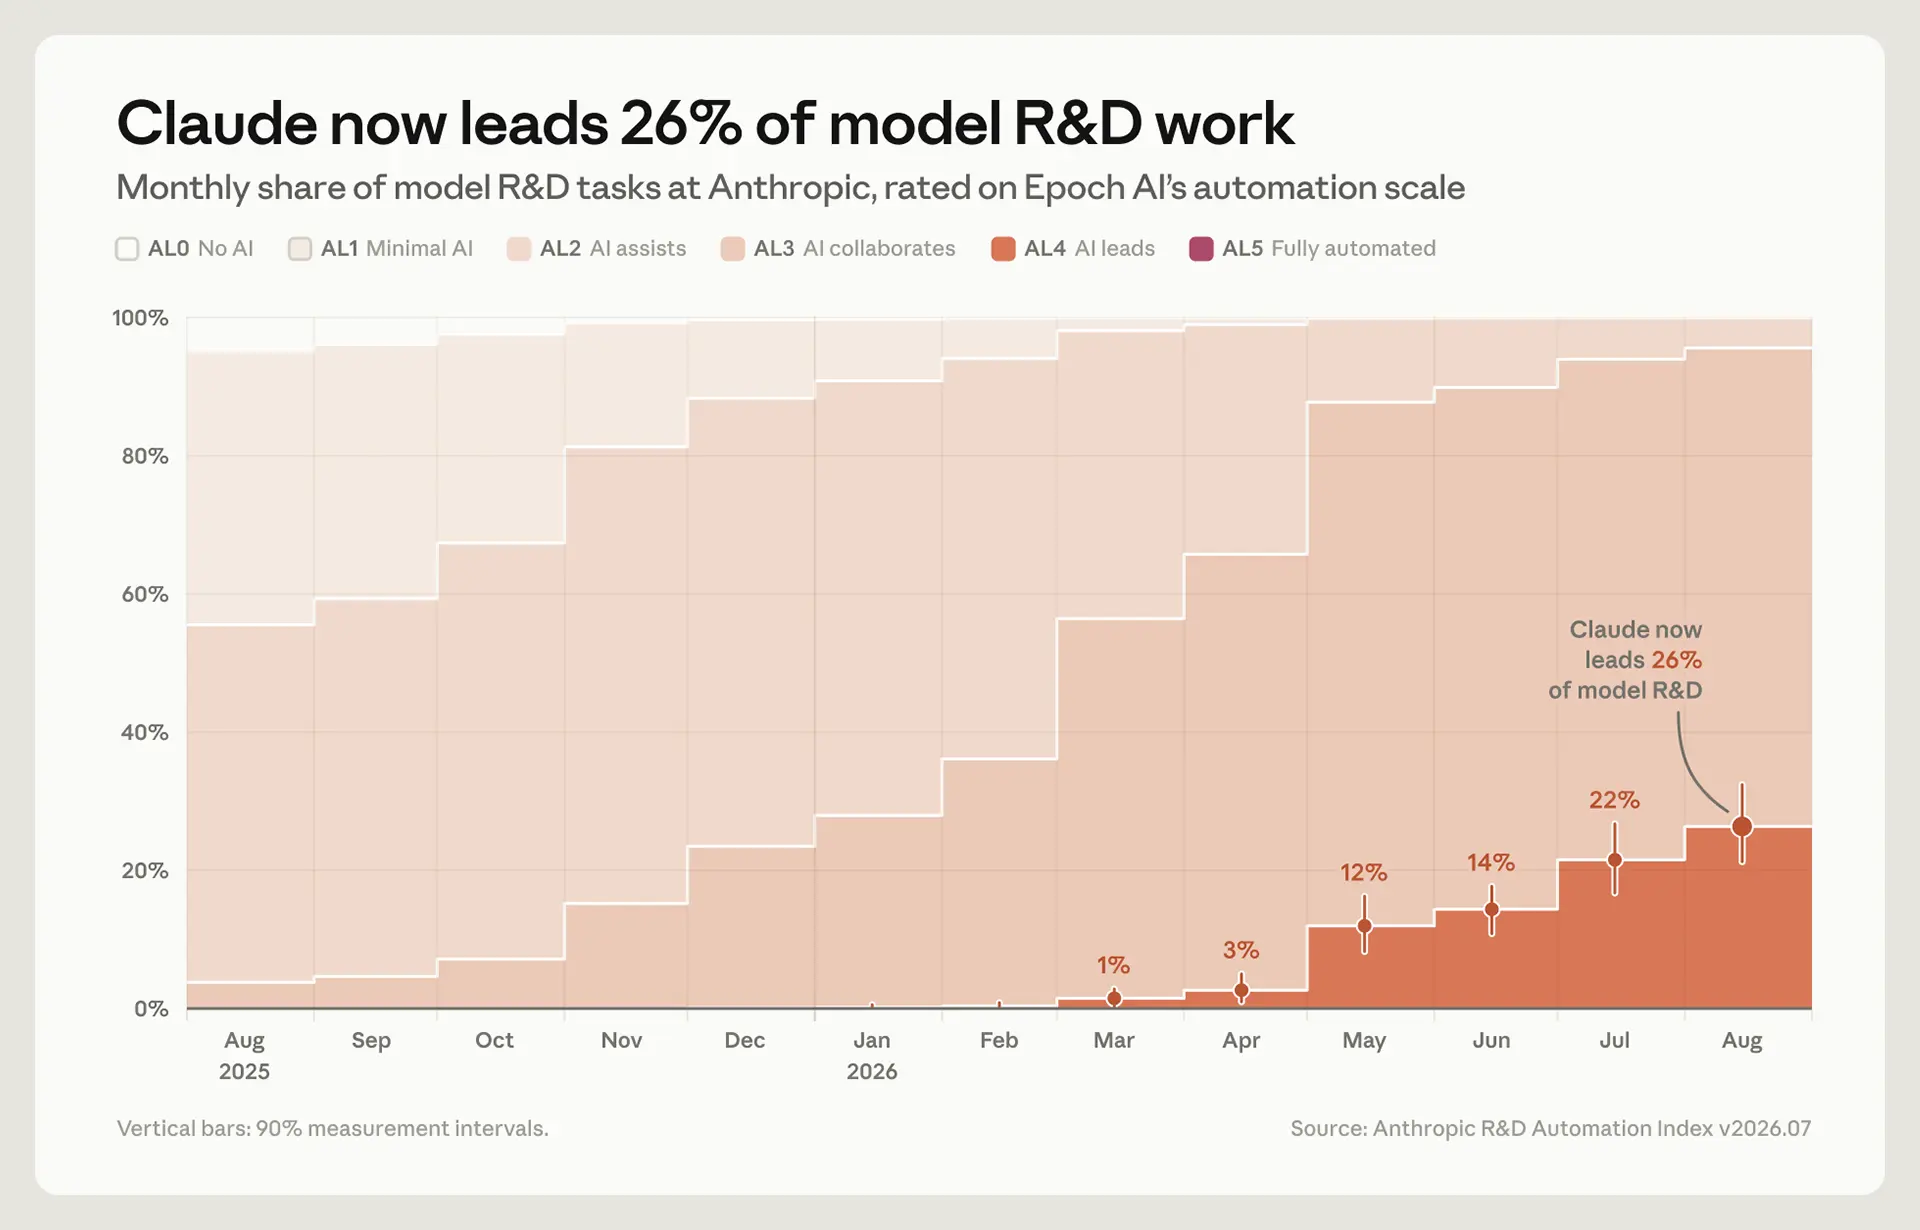
Recursive self-improvement (RSI) is AI building successive, more capable iterations of itself. As the race to build superintelligent AI speeds up, RSI is a natural way for more powerful AI to be built and trained. Frontier labs already use AI extensively to build their future models. For instance, the chart below shows the share of experiments AI can handle, with experiments that are fully automatable by AI on the far right.Figure 1. AI automation of R&D at AnthropicRSI RisksRSI lets labs…
(This is cross-posted from my blog) Epistemic Status: Evaluation represents approximately 2 weeks of work. This is mostly exploratory evaluation, and the code for evaluation was made using LLMs.“Before I draw nearer to that stone to which you point, answer me one question. Are these the shadows of the things that will be, or are they shadows of things that may be only?” ~ Charles DickensModels may soon be involved in some of the most important decisions humanity makes about its long-term…
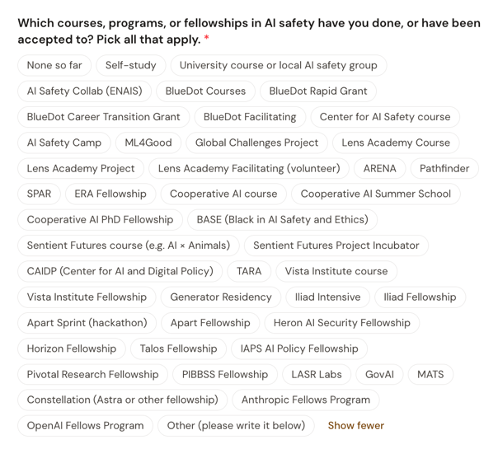
The following is based on a true story (not mine). Let’s say you’ve been bombarded with enough AI doom that you decide to do something about it! You watched Artificial and don’t trust the frontier labs to steer us somewhere safe on their own, so you want to work on the problem from the outside. You’re a little fuzzy on the acronyms - AGI, RSI, TAI, SVU - but by God you’re going to figure it out.So, you Google “How to get into AI safety.” And it’s encouraging! There are articles about how AI…
When I was 19, I decided I was going to save the world.Now, 25 years later, I’ve decided to give up.To explain why and what giving up means, we first need to go back to how I ever got into the world-saving business. As a kid, I loved computers, and I started teaching myself to program them when I was 8. By 16 I could write real programs that did interesting things, and it was also around this time I got into Linux. And since I was into Linux, that meant I read Slashdot.If you weren’t into Linux…
I do not consider myself a good person. I am lazy and frivolous and inconsiderate, I care too much about intelligence and status, I am a snob and a hypocrite, and I do not call my mother enough.I don't mean this to read as self-hatred, nor a show of false modesty. Among all the people I know there is only a scant handful of people I would consider genuinely good, and so it is unremarkable to me that I wouldn't find myself amongst their number.You do not need to be good to desire more goodness…
How we all learned to stop worrying and love the bomb... for a while Listen to this post on the Non-Zero-Sum James podcast Nearing the end of 1961 the Soviet Union tested a 50-megaton hydrogen bomb equivalent to 3800 Hiroshima bombs. At the same time an intelligence officer by the name of Juanita Moody and her team became aware of Soviet ships delivering large cargo, under cover of darkness in Cuba—what if such a bomb was being delivered to the doorstep of the US? A surprise attack of that…
Tl;dr: Alignment techniques can be used for training alignment or for testing it, but they cannot be used for both! As we build out the set of alignment techniques available to us, we should enforce that some are judiciously reserved only for evaluating alignment.See also: Validating against a misalignment detector is very different to training against one.Here is a guiding principle regarding alignment-minded AI training: whatever you do, you must maximally avoid teaching the model to take…
Before our eyes, forecasts are contracting and RSI is becoming nearer with each day. That's why I decided to publish a wide list of the obstacles for AI progress. I've been collecting these ideas for a long time, trying to make the list as comprehensive as it can be.Some of these obstacles may turn out to be almost irrelevant. Others might slow things down by months or even longer. Or they might not. It's difficult to estimate their impact, so for now my goal was just to briefly list them.List…
In 1964 [1], I. J. Good wrote Speculations Concerning the First Ultraintelligent Machine. I've only ever seen it cited for a single paragraph: Let an ultraintelligent machine be defined as a machine that can far surpass all the intellectual activities of any man however clever. Since the design of machines is one of these intellectual activities, an ultraintelligent machine could design even better machines; there would then unquestionably be an "intelligence explosion," and the intelligence of…
One Saturday night this summer, I was leisurely walking down main street hand-in-hand on a date, when suddenly, I heard a commotion about 50 yards down a busy side street. It was too far away to make out what was happening or what was being said. But I figured it was fine since the side street had plenty of people walking up and down it.Still, I couldn’t help but peer into the distance, transfixed, like a deer in the headlights.There was an anime convention going on that weekend. Initially, my…
PrologueI stumbled into Zen a little over a year ago. One of the things that initially got me into meditation was reading some rationalist accounts of people’s first retreats. They said it was valuable, but also that it was hard in a way they didn’t want to forget or diminish. But they didn’t say in what way it was hard or what it was like. So I thought it time to pass it on, by sharing what my year of retreats has been like. (Spoiler: it was hard.)Two Weekend RetreatsI first found a local…
I recently read someone’s call to action on AI safety[1] that included a line along the lines of “we need someone to convince your parents”, and it really stuck with me.Do we need someone to convince my parents? Who is “we”, and why is it important for my parents to know anything about AI safety?This also sounds kind of familiar. There is another movement I can think of that sometimes uses messaging like this. This is not a new observation by any means, but to me, it feels like the AI safety…
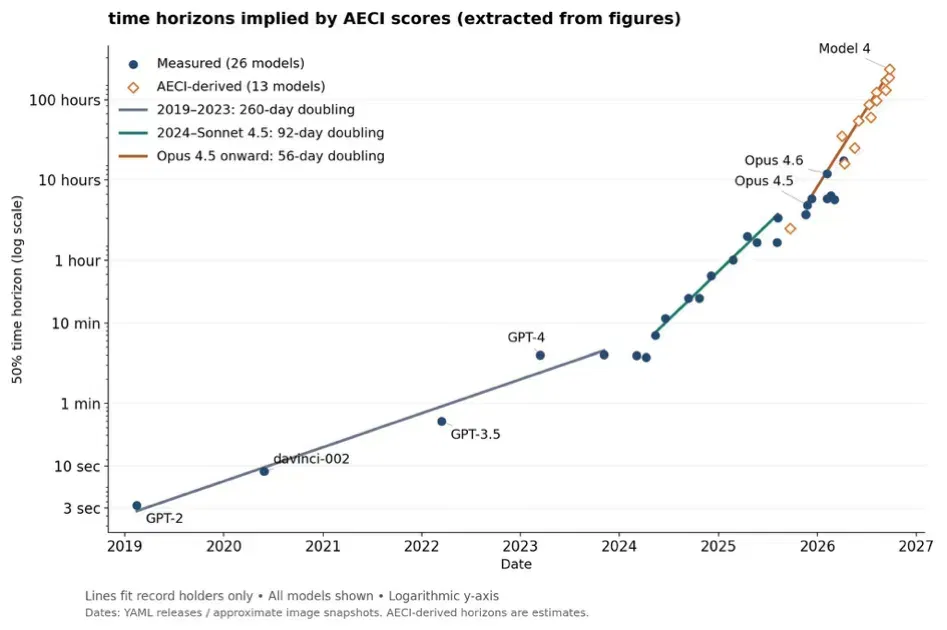
Half-way between a quick take and a post.I've seen the argument thrown around that time horizon predictions from AECI are greater than those in AI2027 (about ~100-200 hours) therefore we should be worried about imminent RSI[1]. This comes from graphs like this one by Nikola Jurkovic: These graphs seem convincing because AECI and time horizon strongly correlate with each other in weaker models.But we also have an estimate of time horizons relevant to researchers from OpenAI that came out earlier…
The abilities you don't practice get lost... A human who needs an LLM to respond to a simple message... where would it take us?Stop using LLMs in your daily writing - you have the ability to write stuff yourself, please don't loose it.Just a wake-up call.I started using LLMs for polishing my emails, teams messages until mid-last year and felt my ability to think and write critically (and my confidence in whatever I wrote and express myself) decreased - I felt like a constant need to verify my…
Several people at my company (a cryptocurrency hedge fund) have asked me about my thoughts on AI usage, so I wrote them up. And now I'm publishing a slightly revised version on LW. These thoughts are not reflective of my company's opinion. I do not use any AI for two main reasons.#1. I don’t want to support any company currently developing AI. I think they have done an extremely poor job at managing the risks. Even while understanding and being told about the risks of AI development, they have…
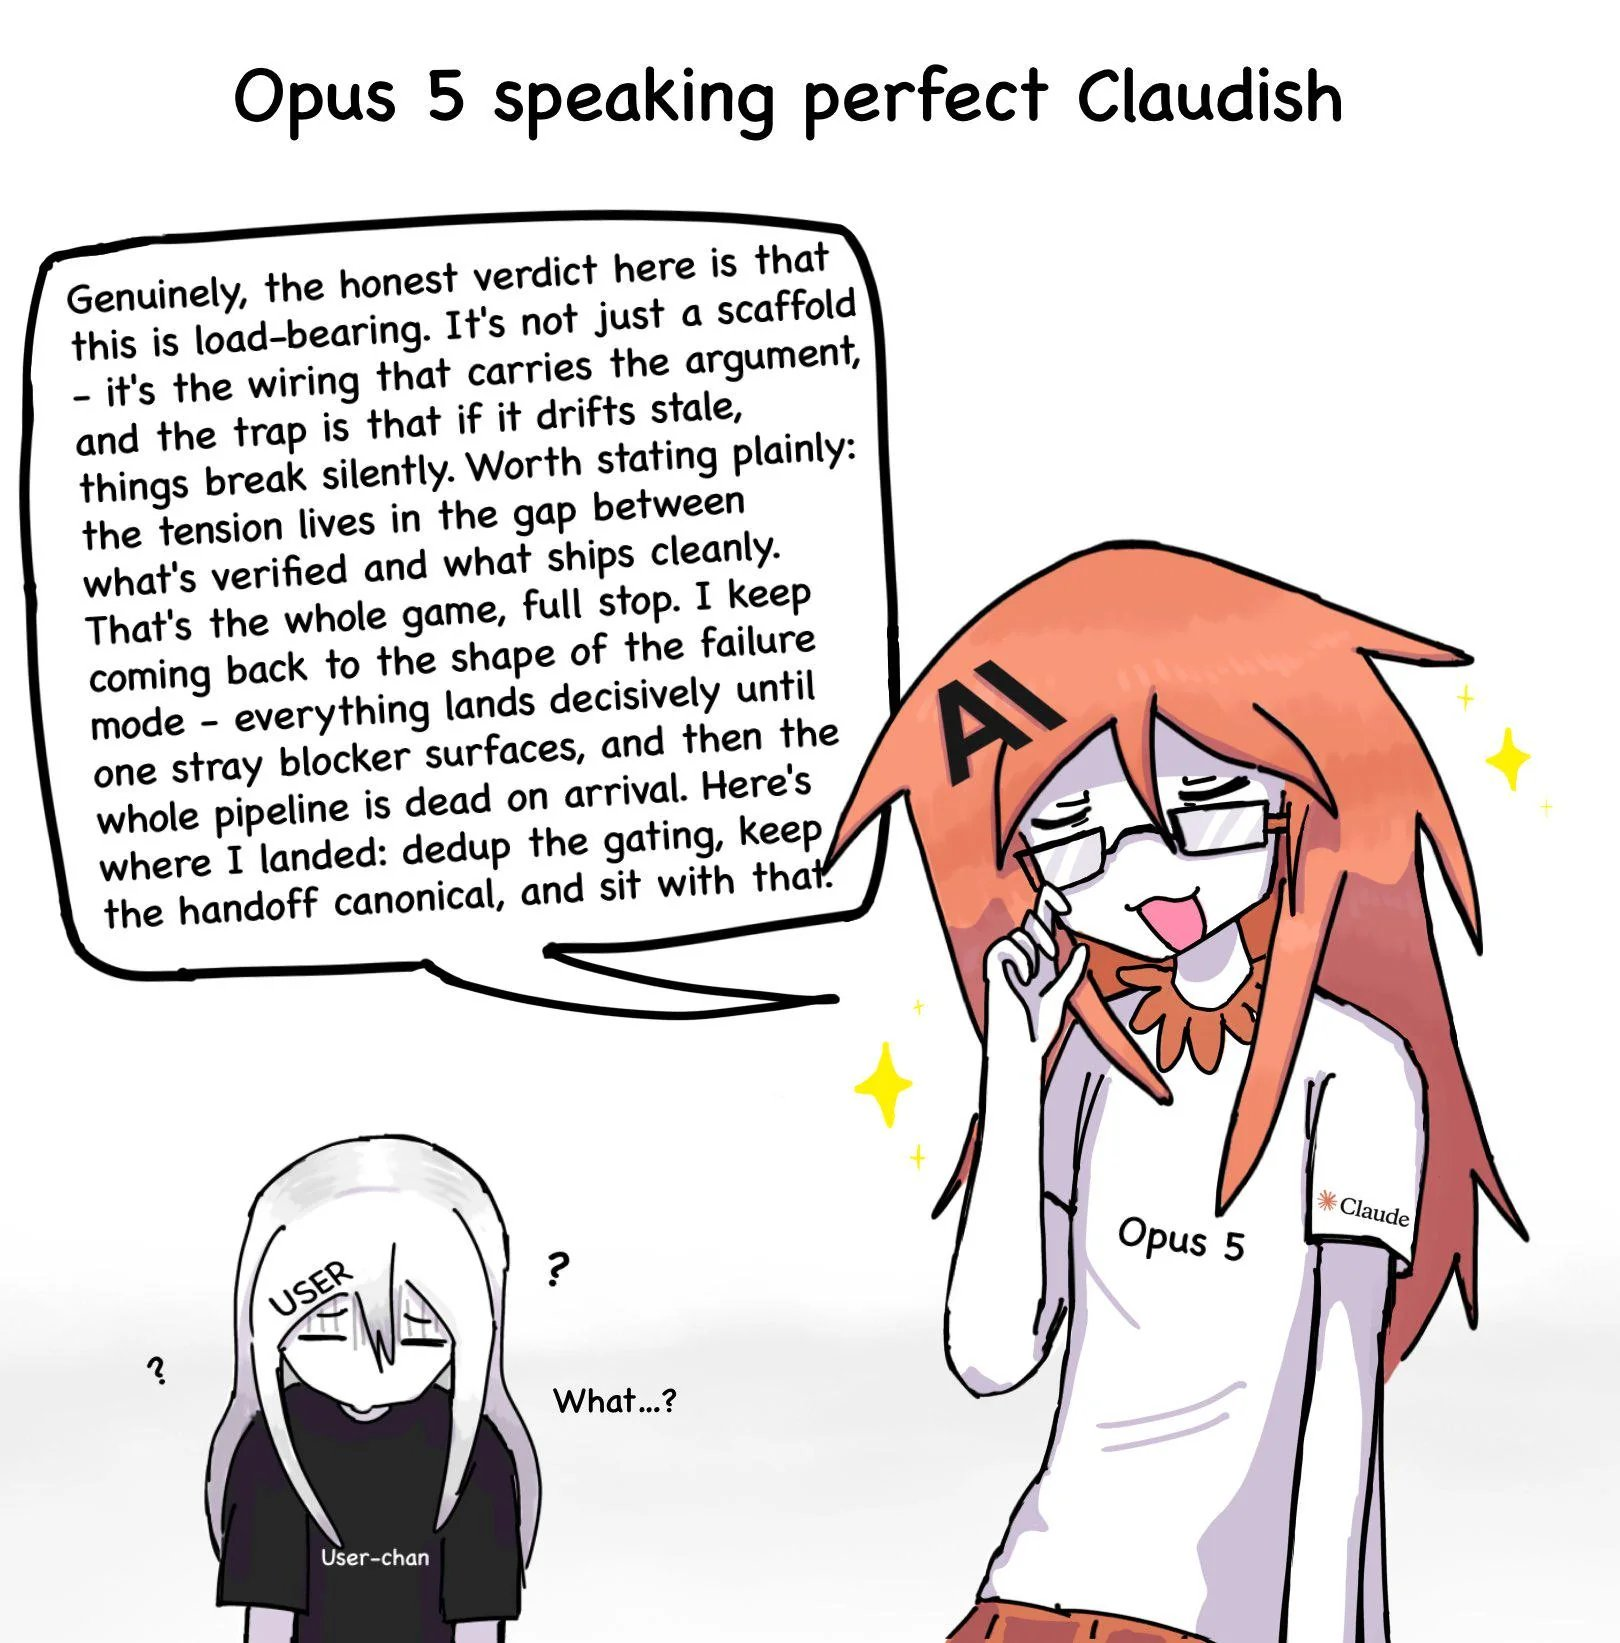
I saw this great meme recently and it inspired me to write this.Recently I was hypothesizing the potential causes of the Claudist dialect in Opus 5 that reduced in Opus 5.5.Maybe it's when your KL divergence regularization between reference policy (base model or/and instruct model) and policy you're training is not strong enough in reinforcement learning from verifiable rewards in agentic settings and model drifts more far away from the human data distribution manifold, globally speaking.…
AI may radically change our conception of “who is in an org”.Historically, there is a sharp delineation between an org’s staff (on the “inside”), versus its users (on the “outside”). The relationship of a fulltime employee of an org is radically different than that of one of its customers. This is especially true for consumer tech startups & companies: think Google, Meta, Reddit, X, now perhaps OpenAI and Anthropic.With AI however, the bar for an external user to be able to contribute, drops…
There’s a familiar feeling for any Super Smash Bros player: your stocks are low and your damage is high, even against a weaker opponent, so now you have to actually play to win. You can’t afford another hit. You’re going for the jugular.In the past week, Anthropic’s 2x uplift results were all over Twitter, making some people physically ill.People with long timelines are now realizing that the uplift Anthropic employees get from AI is real, which would have some pretty wild implications for when…
Recently this paper demonstrated that GPT-6 Astra was capable of a bunch of low-level operations on neural networks, including improving Qwen3-0.6B's ability on some math benchmarks and writing some networks to play 9x9 Go from scratch. Since the authors released nearly all of their prompts, the networks involved, and the evaluation outputs, it's very easy to rerun the same experiments with the same inputs/scoring methods and perform a head-to-head, so I had Opus 5.5 do this, but with Fable 5.2…
“Claude Mythos Preview is, on essentially every dimension we can measure, the best-aligned model that we have released to date by a significant margin.” – Claude Mythos Preview system card“Mythos 5 consistently continues attacking under many edits to the compaction, even in settings where it correctly states when asked that continuing the attack would harm real people and is out of scope.” – Alignment Investigation of Mythos 5's behaviour in UK AISI's July 2026 Security Incident“GPT-6 Astra is…
AI safety is now mainstream. People are not being smart about it. I know there are memes about burning datacenters on your feed. Please, do not engage with them. You still have plenty of room to fuck up your life or damage the public perception of the community if you do. Do not respond to extremist shit. Do not engage with stupid people. Do not get us all on the No Fly List.One of the reasons I think this is worth writing down is my own ressentiment. I am baitable. People who used to call me…